Qwen3-TTS
Alibaba Qwen's open-weight text-to-speech models in 0.6B and 1.7B sizes, with 3-second voice cloning, voice design from a text description and streaming latency as low as 97ms, plus a paid API on Alibaba Cloud.
Short description
Qwen3-TTS is a free, open-source text-to-speech model from Qwen, Alibaba's AI model family, licensed Apache-2.0 (verified on GitHub). It can copy a voice from a very short clip or invent a new one from a written description. Hobbyists and creators run it on their own GPU to replace paid ElevenLabs cloning, while businesses can use Alibaba's cheap hosted version on Model Studio.
Features
3-second voice cloning: The Base models clone from about 3 seconds of reference audio, and you can save and reuse a clone
Voice design: Creates a new voice from a plain-language description with the 1.7B VoiceDesign model, and can be combined with cloning
CustomVoice presets: Built-in speakers that follow style instructions for tone and emotion
10 languages: Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish and Italian, plus Chinese dialects
Low-latency streaming: First audio can start after one character, with end-to-end latency as low as 97ms per the vendor
Fine-tuning: The Base models can be trained further on your own data
Release: Open weights released January 22, 2026 and the Model Studio API is generally available. Uses a 12Hz tokenizer.
Pricing
How you pay: Free open weights to self-host, or a pay-per-character Alibaba Cloud API
Free: $0 self-hosted under Apache-2.0. The API gives 110K free characters for 90 days.
API: $10 per 1M characters, or $13 for real-time, vs ElevenLabs' $40-80
Voice cloning: $0.01 per cloned voice on the API
Caveat: Chinese, Japanese and Korean characters are billed as two characters each
Integrations
Platforms: Self-host on your own GPU or use the cloud API on Alibaba Cloud Model Studio in Singapore/International and Beijing regions. There's no official GPU memory figure, but one user runs it on a 12GB laptop GPU (RTX 5070 Ti)
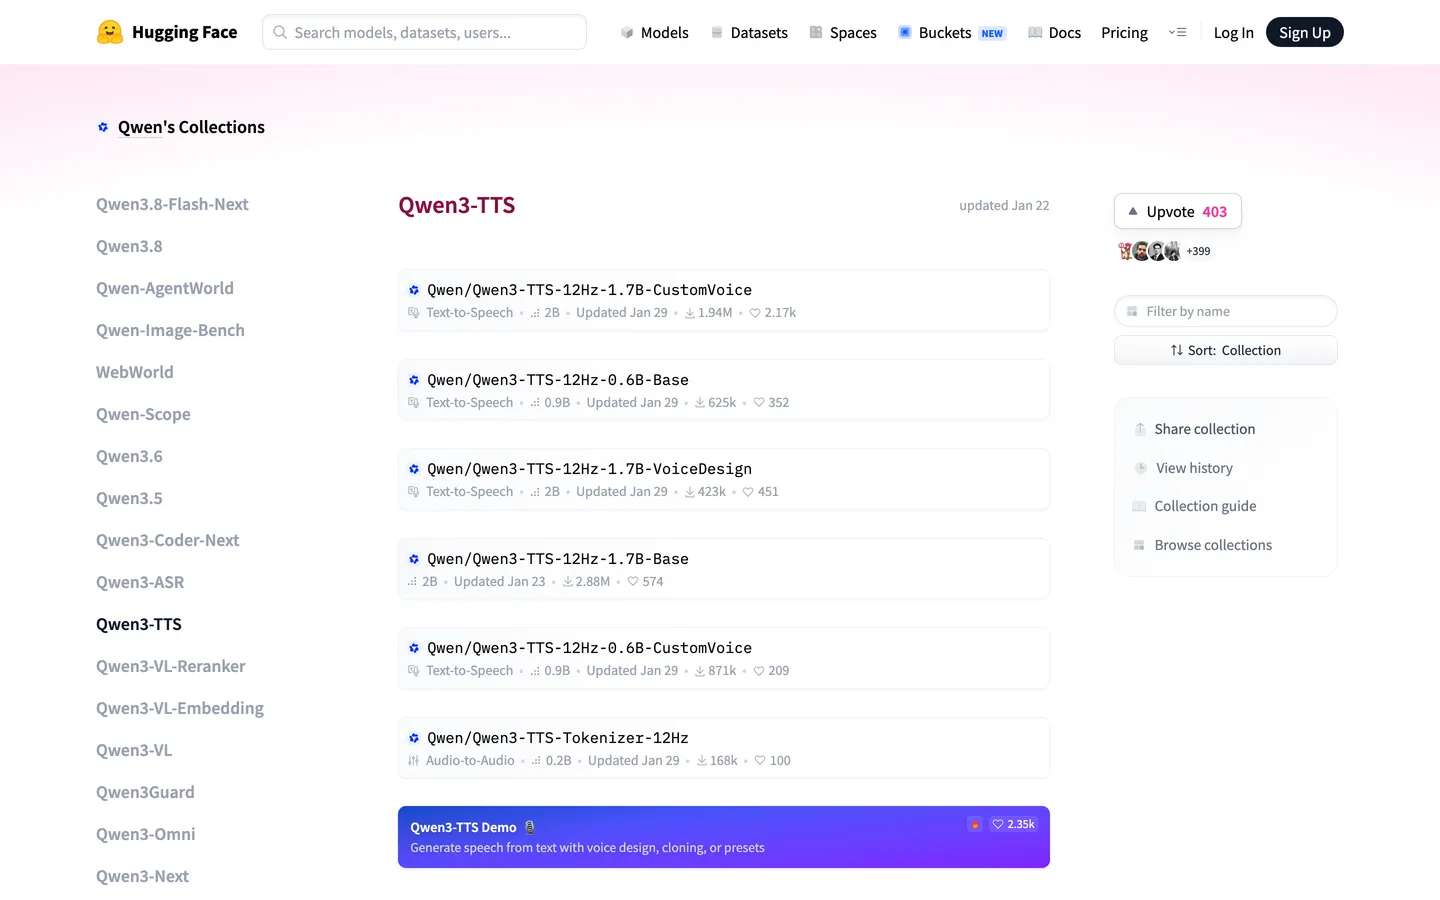
Model downloads: Weights on Hugging Face and ModelScope, with code at github.com/QwenLM/Qwen3-TTS
Local demo: A Gradio web demo (qwen-tts-demo) for testing in your browser
vLLM-Omni: Supported from release day for offline generation, with online serving planned
ComfyUI community nodes: A common way people run it inside the ComfyUI visual workflow tool
Alibaba Cloud APIs: Model Studio and DashScope offer real-time, voice-cloning and voice-design APIs, documented at alibabacloud.com/help/en/model-studio/qwen-tts
QwenVoice: A community-built Mac app
Platforms
- Self-hosted (GPU)
- Alibaba Cloud Model Studio API
- Gradio web demo
What users love about Qwen3-TTS
Replaced a paid ElevenLabs plan: A YouTuber set it up in ComfyUI on a 12GB-VRAM laptop and renders a full PDF page per pass, after Chatterbox failed on long generations
Strong cloning from a few seconds: Clones closely match the reference voice from very short clips, which is why it keeps coming up as a free stand-in for ElevenLabs cloning
Speed can be fixed with community forks: Forks using torch.compile and CUDA graphs report about a 6x speedup and first audio in under 0.1 seconds on an RTX 5090, enough for streaming
What users complain about Qwen3-TTS
Flat, rushed delivery: Almost no emotion and no real speed control. Cloned voices always talk faster than the sample, turning a one-minute script into 41-48 seconds, and no setting fixes it.
10x slower than real-time out of the box: RTX 5090 owners see generation 10x slower than real-time with the GPU nearly idle, and a 3060 needs about 5 seconds per second of audio without community forks
Random glitches that need re-rolls: It sometimes switches to a different speaker, drops the last few words of long passages, or adds laughter and words not in the script
Accent carries across languages: A sample in one language carries its accent into another, and mismatched languages make speaker switching more likely
Hard setup for non-specialists: FlashAttention builds, a hard-pinned transformers version and patchy support for Mac M4, AMD and Intel Arc GPUs
Similar tools
Alternative AI options